Technologies: Rust, React, Python, DuckDB, OCR, PDFium, Native runtimes, OpenAPI
Published
Local OCR with the Baidu model ecosystem
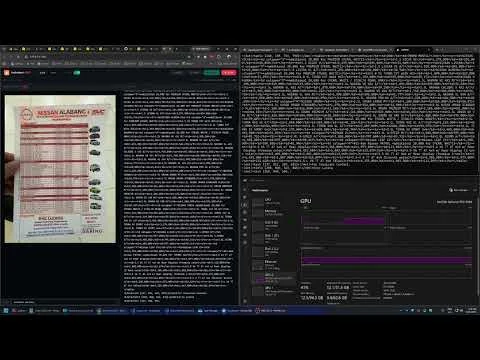
An OCR application demonstration related to the local document-processing work that developed into Trapo.
Systems & platforms · Experiment
A local document workbench for inspecting OCR text, page images, regions, and processing history.
Technologies: Rust, React, Python, DuckDB, OCR, PDFium, Native runtimes, OpenAPI
Trapo processes local PDFs and images and presents page previews alongside extracted text, bounding boxes, spans, and diagnostics. Local persistence retains document data and the history of ingestion runs.
The Agus Works prototype used Python, FastAPI, DuckDB, and local document readers including Docling, MinerU, and Infinity Parser2. It stored file hashes, structured output, chunks, and page regions. The subsequent workbench uses a Rust server, a React interface, PDFium rendering, local persistence, and runtime and model loading. Its repository retains the name baidu-unlimited-ocr-portable.
The workbench persists OCR stream events before broadcasting them. After a refresh, the interface reconstructs completed activity and continues receiving new events. Page-region anchors connect extracted spans to the document preview.
The project uses existing OCR models and runtimes for ingestion and inspection. Graph extraction and graph-based retrieval remain planned extensions.
Published
An OCR application demonstration related to the local document-processing work that developed into Trapo.